The Manuscript Digital Divide: What Drives Selection in Digitization?

Originally presented at the University of Rochester on invitation of the Curating the Middle Ages Working Group, Central New York Humanities Corridor, December 2023. It has been lightly edited. Images are slide screenshots. Except where otherwise stated, all information is current as of November 2023.

Good afternoon, and thank you to Anna and Irina for inviting me to speak today. I appreciate the freedom to choose the topic of my lecture, and I opted to delve into something new. As a result, I find myself posing more questions than providing answers. However, this exploration may bring about greater clarity and direction for future research.

Today, I’ll be discussing what I term the “manuscript digital divide.” The central question revolves around what influences the selection process in digitization. This query arose during my engagement with Suzanne Paul’s book chapter on the curation and display of digital medieval manuscripts in the Cambridge Companion to Medieval British Manuscripts.

Who Decides What Gets Digitized?

While the chapter broadly covers manuscript digitization, Paul highlights a critical aspect: who decides what gets digitized?

Paul says: “Although the creation of digital images of medieval manuscripts has been transformative, it is important to acknowledge that at this point in time, only a very small proportion of the medieval manuscripts that survive as a whole or in fragmentary form have been digitized. Why and how were these ones selected?” (Suzanne Paul, “The Curation and Display of Digital Medieval Manuscripts” The Cambridge Companion to Medieval British Manuscripts. Cambridge University Press, 2020. pp. 267 – 283)

Paul continues by making two claims:

“Very few institutions fund digitization of their collections from their core budget; by and large, the costs of digitization have to be met from external sources.”

And

“Early manuscripts, vernacular manuscripts, illuminated manuscripts, and those with illustrious provenance are at the front of the queue for digitization.”

Now, let’s delve into these two aspects—the funding question and the selection of manuscripts for digitization. Regarding funding, the common belief is that digitization is constrained by budget limitations. Many institutions rely on external sources, be it government funding, grants, or donations. For the sake of simplicity in this discussion, I’ll refer to this as “budget.”

The second point concerns the priority given to certain manuscripts for digitization, with the specific examples given as early, vernacular, illuminated, and those with illustrious provenance.

This paper will explore both the funding and selection processes in detail.

The History of Manuscript Reproduction

Before delving into these claims, let’s briefly touch upon the history of manuscript reproduction. This context is crucial for understanding the evolution of manuscript digitization.

I won’t go into detail here, but I recommend exploring Sian Echard’s talk “‘Secure from the Ravages of Time’: Antiquarian Avatars of Medieval Manuscripts” from the 14th Annual Schoenberg Symposium in 2021 and Bridget Whearty’s book Digital Codicology: Medieval Books and Modern Labor (Stanford University Press, 2022) for a deeper historical perspective.

Screenshot from Sian Echard’s talk ‘Secure from the Ravages of Time’: Antiquarian Avatars of Medieval Manuscripts comparing early facsimiles of a manuscript illumination

Shifting to a historical snapshot of manuscript digitization around 20 years ago, I want to share insights from a national survey I conducted for my master’s paper: Medievalists’ Use of Electronic Resources: The Results of a National Survey of Faculty Members in Medieval Studies (University of North Carolina, November, 2002). This survey asked faculty members in medieval studies about their use of electronic resources. Notably, the resources available in 2002 were limited compared to today.

Projects like “Images of Medieval Manuscripts of the Bodleian Library, Oxford” involved scanning images from existing film, a common practice until the early 2000s. Other projects, such as “Early Manuscripts at Oxford University” and “DScriptorium,” showcased a mix of complete digitized manuscripts, selected images from institutional collections, and additional information such as transcriptions and translations. DScriptorium was a project of Dr. Jesse Hurlbut of Brigham Young University, and should not to be confused with Digital Scriptorium (DS). DS was established in 1997 but wasn’t mentioned in the master’s paper, which seems like an oversight 20 years later. DS organized under a consortium in 1999, which set it apart from the institutions that focused on their own collections.

The Magna Carta at the British Library and the Aberdeen Bestiary were significant digitization projects, offering high-resolution images when many projects did not. Additionally, projects like The Electronic Beowulf and The Canterbury Tales Project focused on individual manuscripts, high-resolution images, and added information.

In 2002, the emphasis was on institutional collections, thematic focus, and to a lesser extent on consortia collaboration, as seen in DS. The Electronic Beowulf included images taken under ultraviolet light, so we can see that in 2002 advanced digital imaging techniques were already part of the conversation.

Digital Manuscript Landscape in 2023

Let’s turn to the contemporary landscape and the data I sought for my research. To find relevant information, I turned to the Digitized Medieval Manuscripts Project, abbreviated as DMMap. This project serves as an invaluable resource by mapping institutions that have digitized manuscripts available, particularly focusing on Western medieval manuscripts.

DMMap originated around a decade ago in the Netherlands, initiated by graduate students. The project involves crowd-sourced data, constantly updated with the latest blog post in May 2023 (Note: In December 2024, the May 2023 blog post is still the most recent one). While acknowledging potential data inaccuracies due to its crowd-sourced nature, it provides a valuable starting point to seeing which institutions have digitized their manuscripts.

The project consists of two primary components: the map and the data. The map visually represents the distribution of institutions globally, while the data offers detailed information about each institution’s digitized manuscripts. Notably, I contacted the project team, and they confirmed the ongoing activity and responsiveness to reported issues. (Note: In December 2024, updates to the data have been made as recently as November 27, 2024)

The map showcases a concentration of institutions in Europe, with representation from the United States, UK, Canada, Japan, Australia, New Zealand, and Brazil. Clicking on a specific institution reveals options to explore digitized manuscripts directly or access additional data.

Clicking “Explore additional data” to visit the library’s information page.

A tangent. When I was preparing for this talk in November 2023, I selected the National Library of Wales as my example (for reasons that will be clear later in the talk). But when I clicked on that green button that says “Go to the digitized manuscripts,” I was disappointed to find that the link no longer worked, and I got an error message at the library website.

I went back to the previous page, and found the yellow “Report Data Issue” option.

I filled in a report, and within a couple of days the link in DMMap had been updated to point to the correct page on the NLW website – and it still works in December 2024.

The data section provides a comprehensive view, allowing users to filter based on institution, free cultural works, and quantity (that is, the number of digitized items).

They also provide a data spreadsheet, which I downloaded for further analysis.

My preliminary crunching of the data involved evaluating the number of institutions with digitized manuscripts. Out of 578 institutions (Fisher Library, U. Toronto, was listed twice), spanning 10 countries, the distribution varies, revealing the prevalence of digitization efforts in certain regions. I started by looking at how many institutions in are represented by each country. I didn’t find this information particularly surprising. Many smaller countries have few institutions included in DMMap, while those that have more institutions represented are larger countries, and/or countries known for their manuscript collections and their digitization efforts (Numbers as of November 2023):

Number of institutionsCountry/Countries
1Armenia, Brasil, Bulgaria, Croatia, Iceland, Japan, Norway, Slovakia, Vatican, Wales (10 total)
2Denmark, Hungary, Portugal, Romania, Russia (5 total)
3Canada, Estonia, Finland, New Zealand, Sweden (5 total)
5Scotland
6Czech Republic
7Poland
9Australia
11Austria, Belgium (2 total)
15Spain
18Ireland
22England
30Italy
34Netherlands
69USA
75Switzerland
82Germany
149France

Digitization Funding

As a reminder, here is Paul’s claim about digitization funding:

“Very few institutions fund digitization of their collections from their core budget; by and large, the costs of digitization have to be met from external sources.”

I started with with Switzerland. The E-codices project stands out due to its commitment to digitize every manuscript in Switzerland, or manuscripts in other countries that were made in Switzerland.

There are 75 institutions total in Switzerland listed in DMMap. The Congregation du Grant-Saint-Bernard also has its own site listed in DMMap, and The Domschatz der St. Ursen-Kathedrale is in Manuscripta Mediaevalia (Handschriftenportal in December 2024), an online portal for German collections. 74 of these institutions are included in e-codices (Congregation du Grant-Saint-Bernard is not included, but Domschatz der St. Ursen-Kathedrale is).

Looking at data from e-codices itself, we can see that DMMap doesn’t include data for every institution in e-codices. There are 86 institutions from Switzerland in e-codices, with 2,806 total manuscripts. While this means the average institution in Switzerland would have 32.6 manuscripts, we all know that’s not the case. 48 of those 86 institutions have fewer than ten manuscripts, and St. Gallen, Stiftsbibliothek is the outlier on the other end, with 841 manuscripts total.
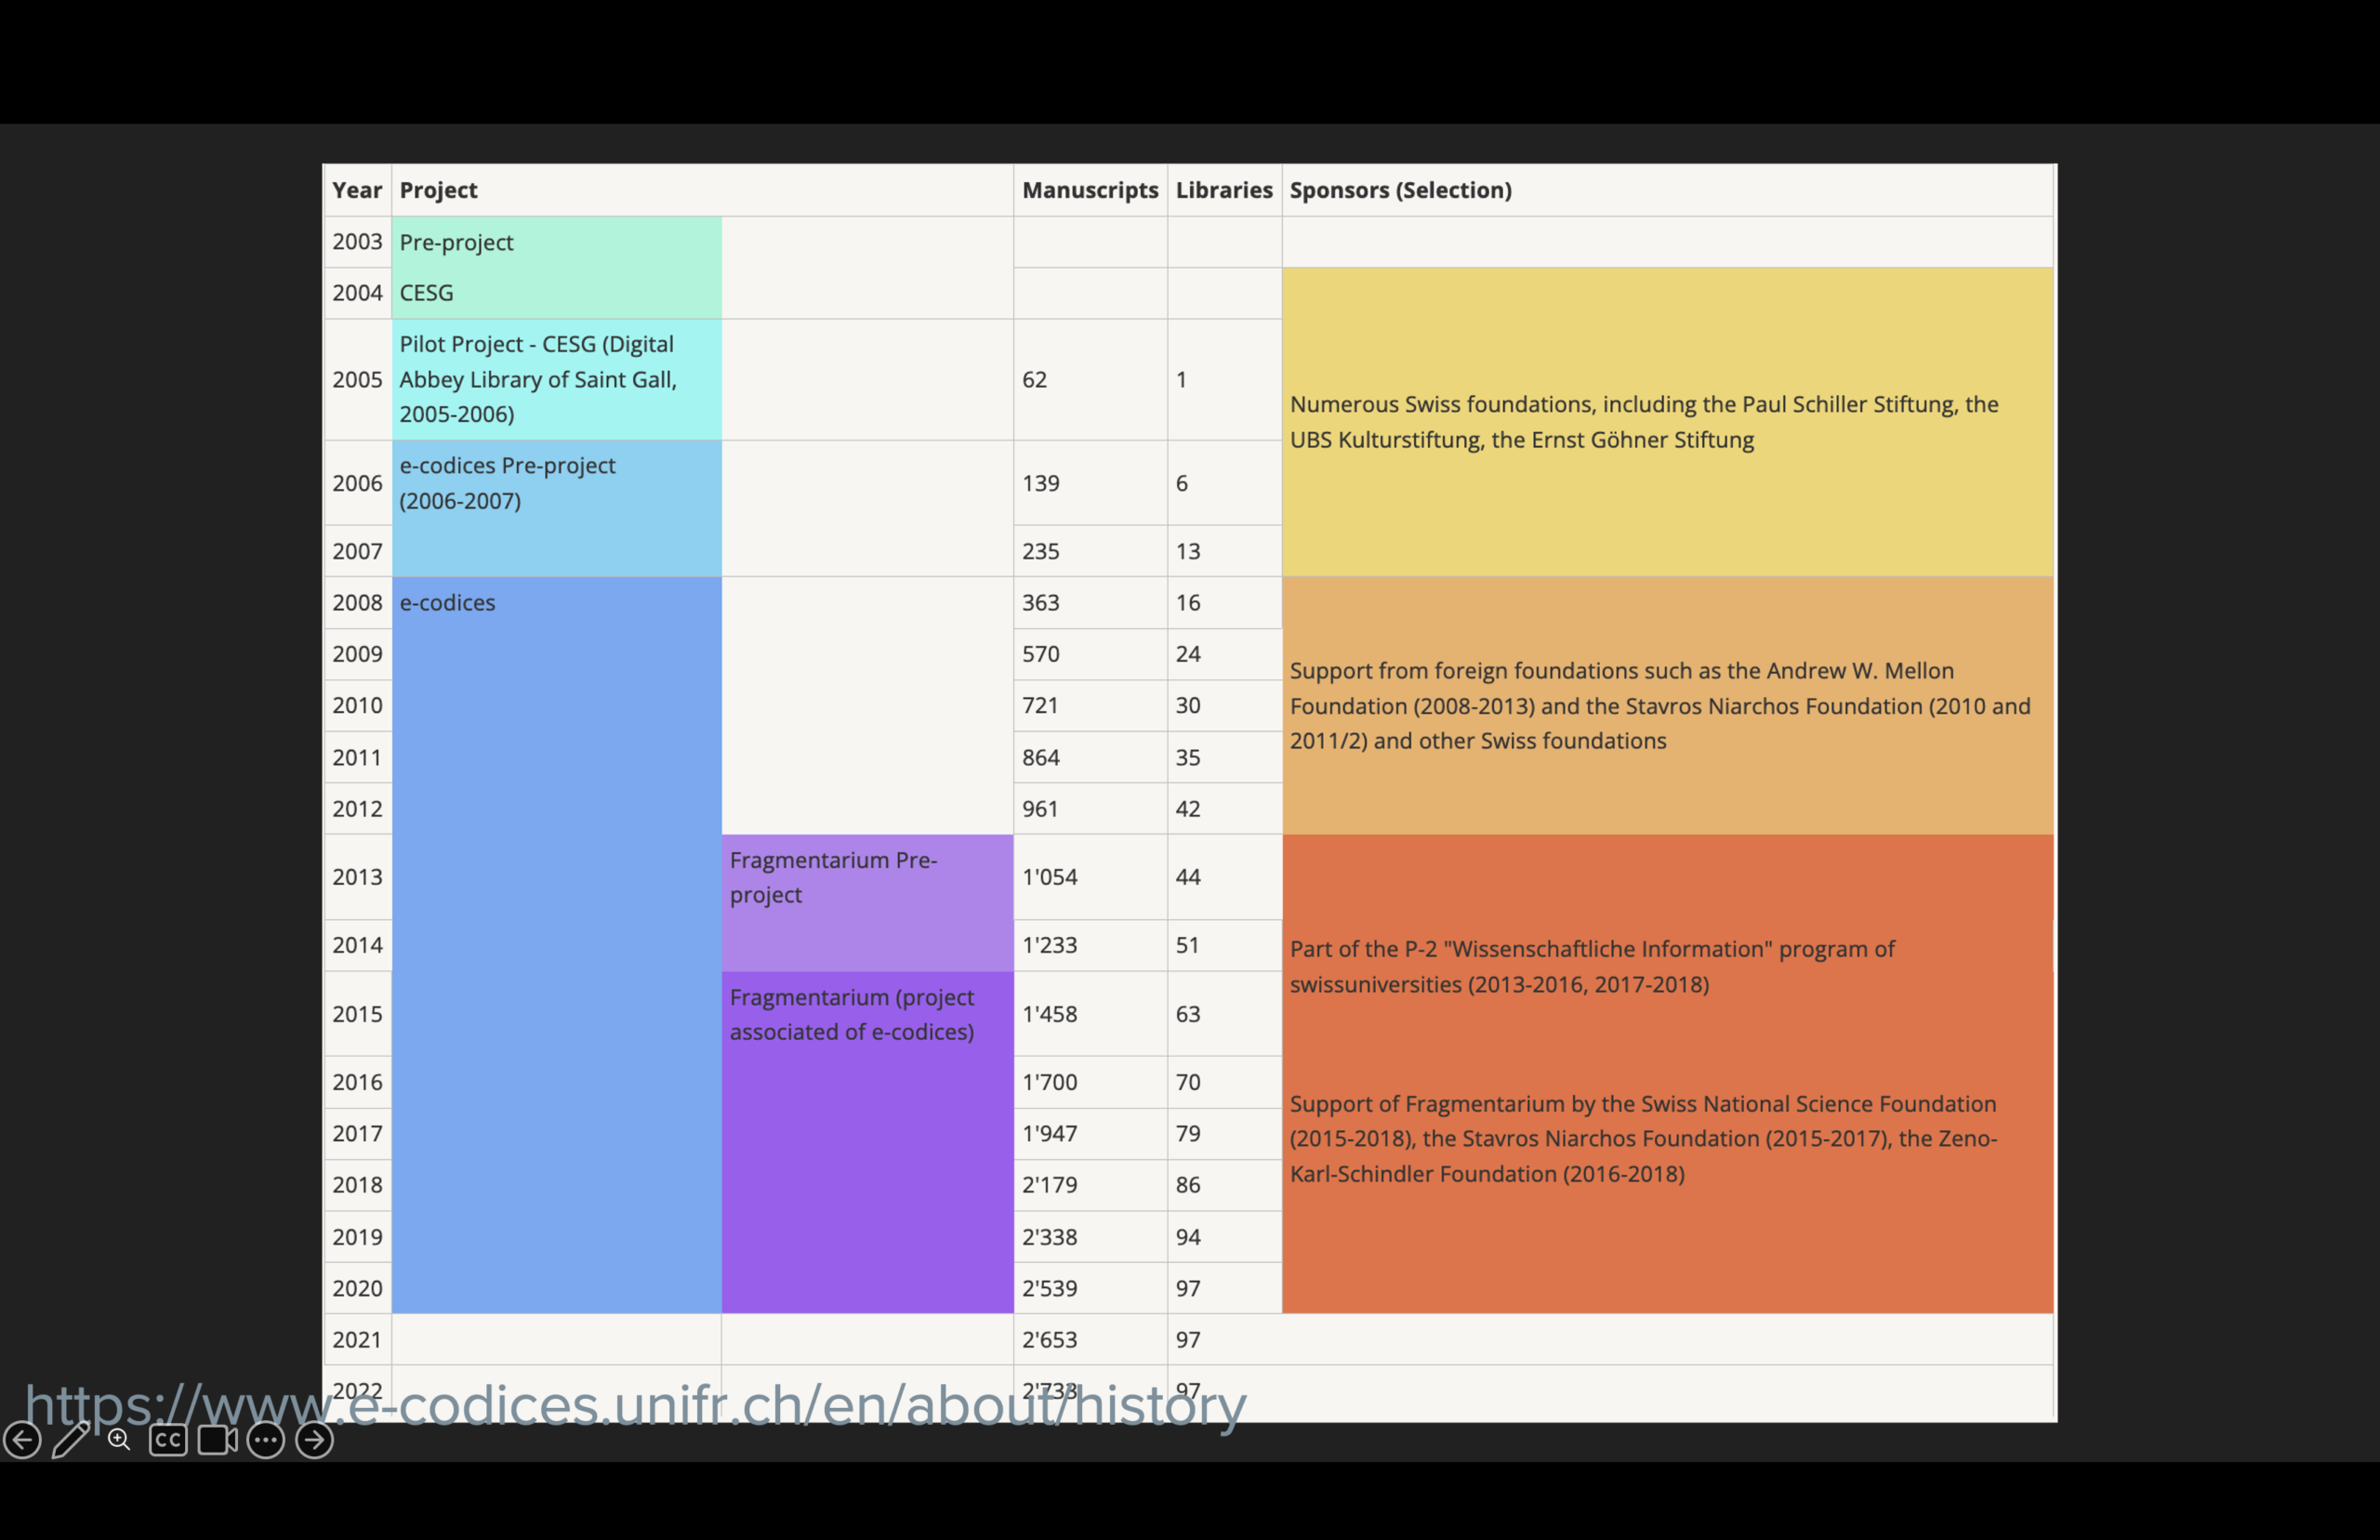
But what about funding? Funding for e-codices has come from many different sources over the years. There are a couple of different sources for tracking funding information. The chart of selected sponsors from the project’s beginning, which is on the “Brief History” page of e-codice’s “About” section, includes (since 2003) various Swiss foundations, Andrew W. Mellon Foundation Foundation, and the Stavros Niarchos Foundation. However this chart is headed “Sponsors (Selection)” so there may be other small foundations not named. There is also a list of current supporting institutions, which as of January 2025 includes many more foundations. The funding for e-codices has been and continues to be substantial.

I want to point out three things about what e-codices has done (beyond, or perhaps in addition to) its funding – in fact, these things no doubt contribute to the great success of this program.

  1. They digitize complete manuscripts, not portions of manuscripts (say, only the illuminated pages). Yes, it is usual today to digitize complete manuscripts, but in 2003 this was not the case.
  2. They digitize only Swiss manuscripts (manuscripts in or from Switzerland) which limits the scope.
  3. The power of building a strong consortium to bring in additional funding and to help keep the project successful over the long term.
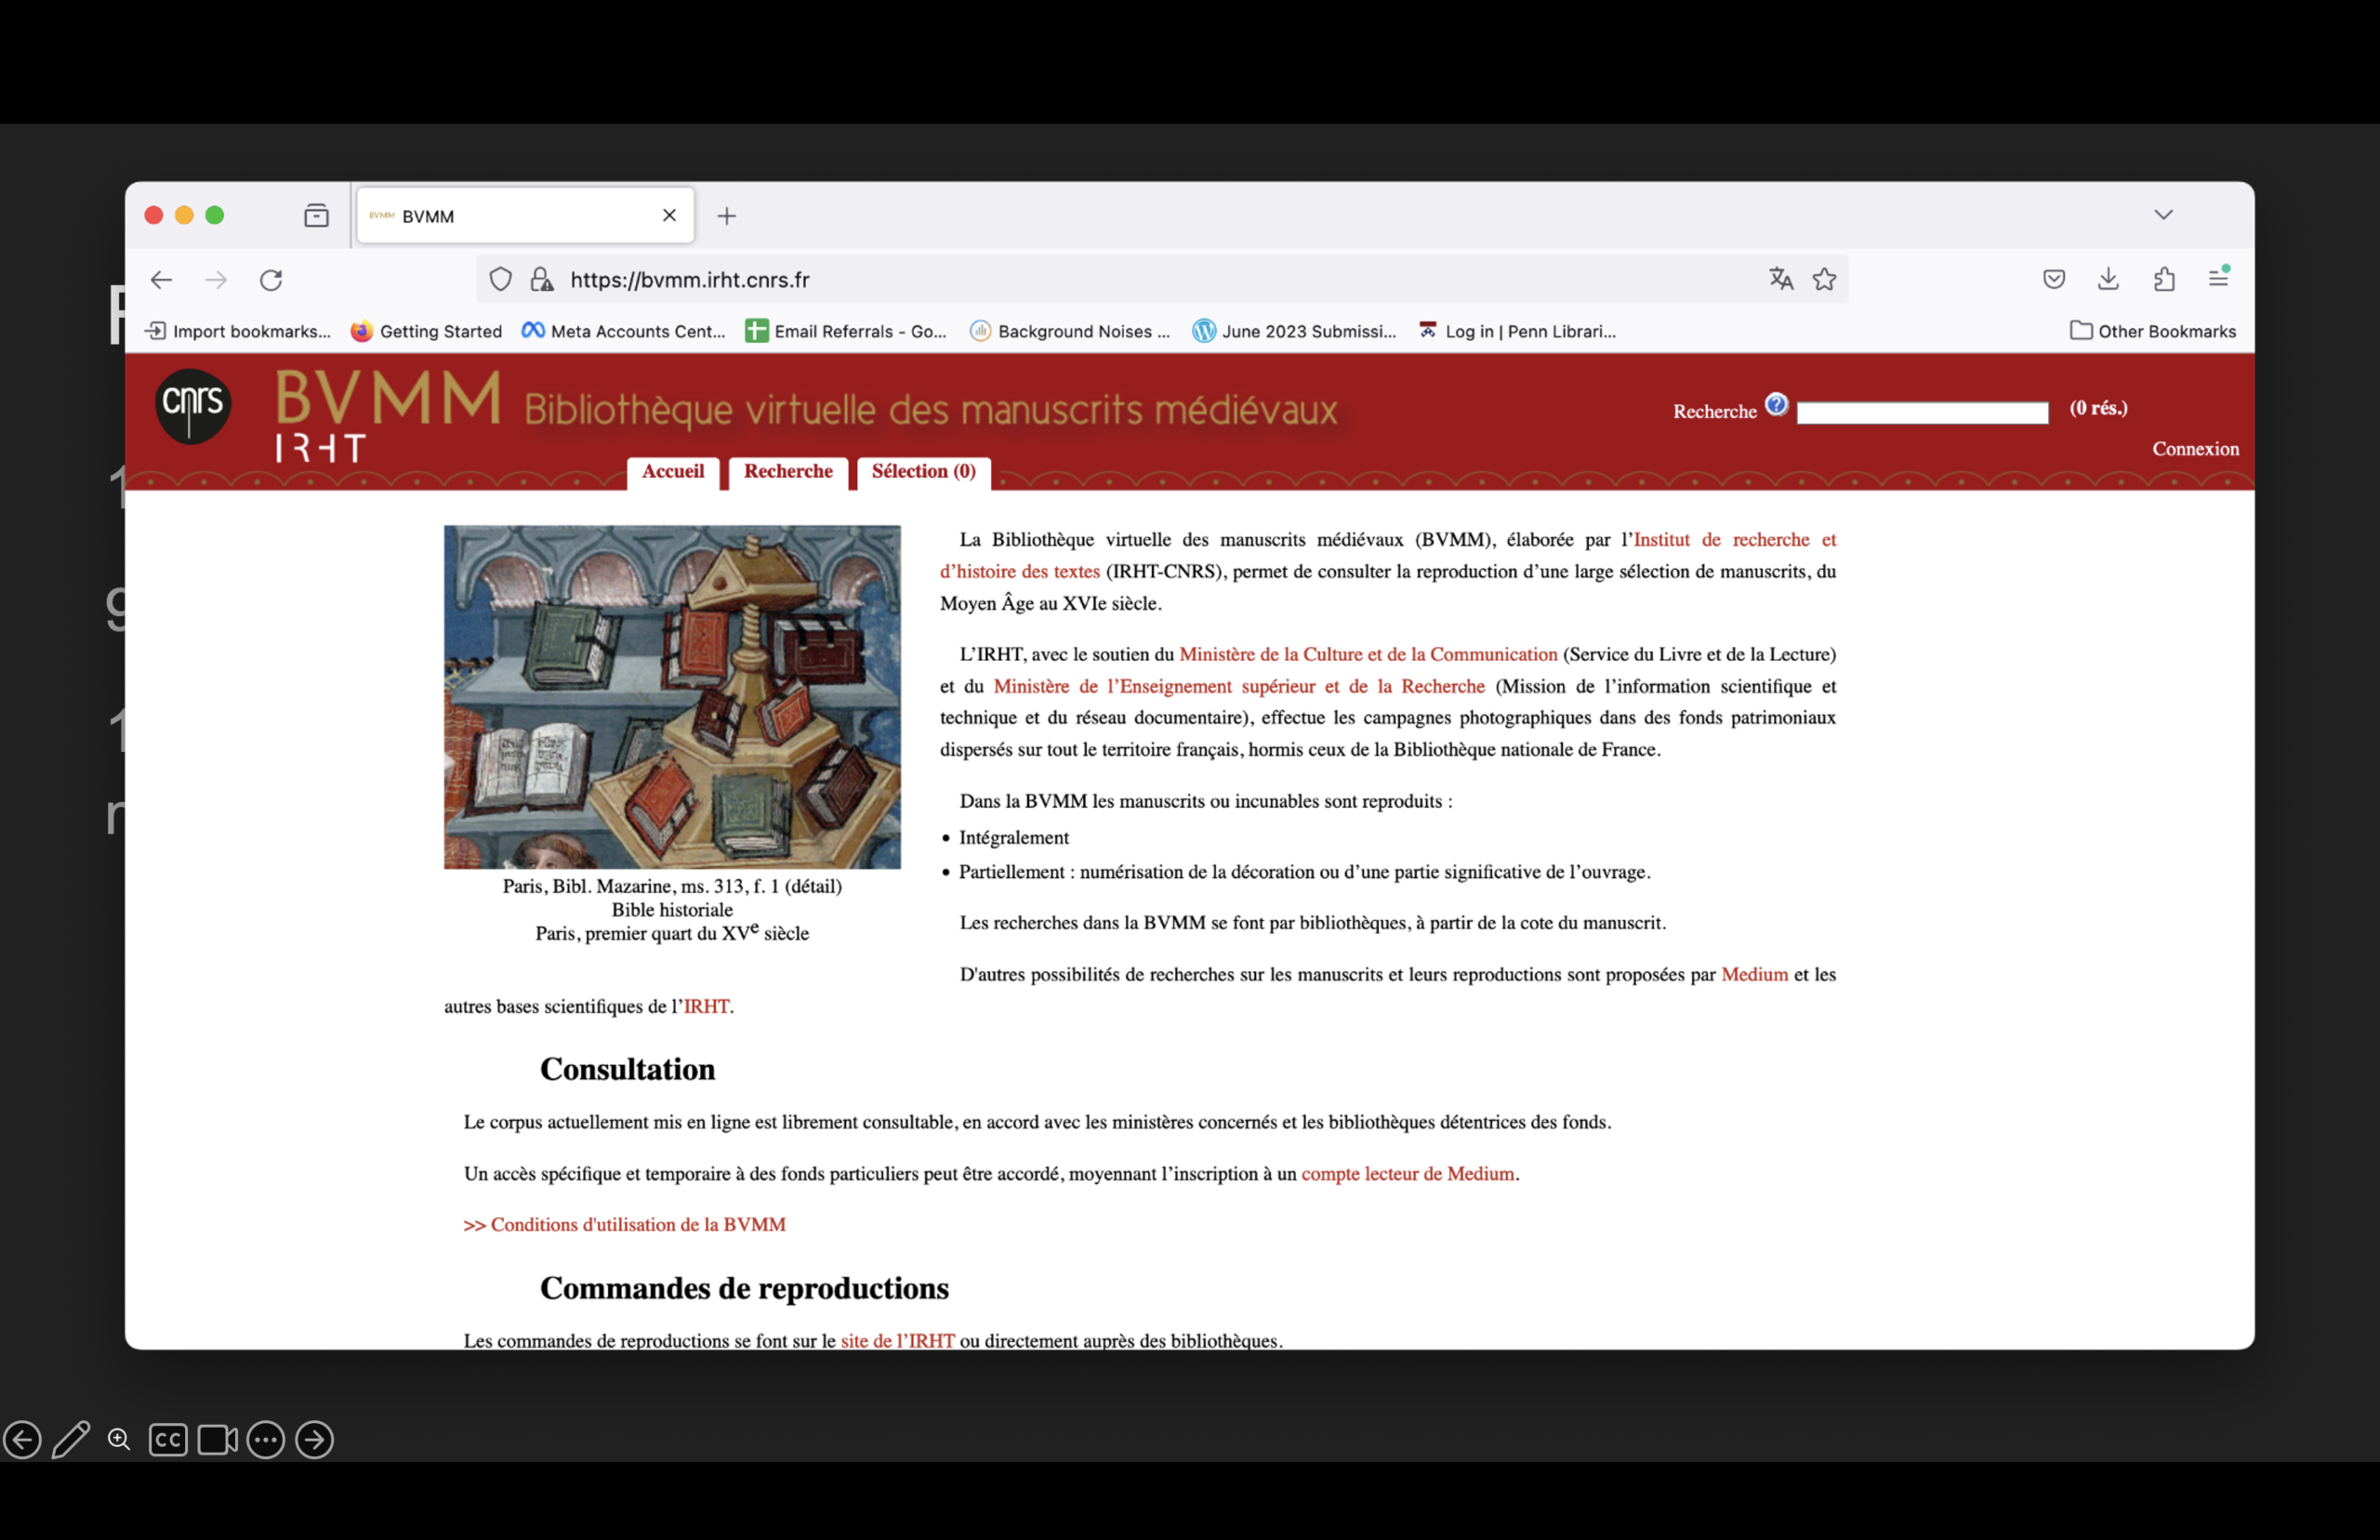
France, with 149 institutions, presents a similar scenario. The CNRS BVVM project, funded by the French Ministry of Culture and Ministry of Research, exemplifies the power of consortia in enabling smaller libraries to participate in large-scale digitization efforts. 118 of the manuscript-holding institutions in France are members of the CNRS BVVM.
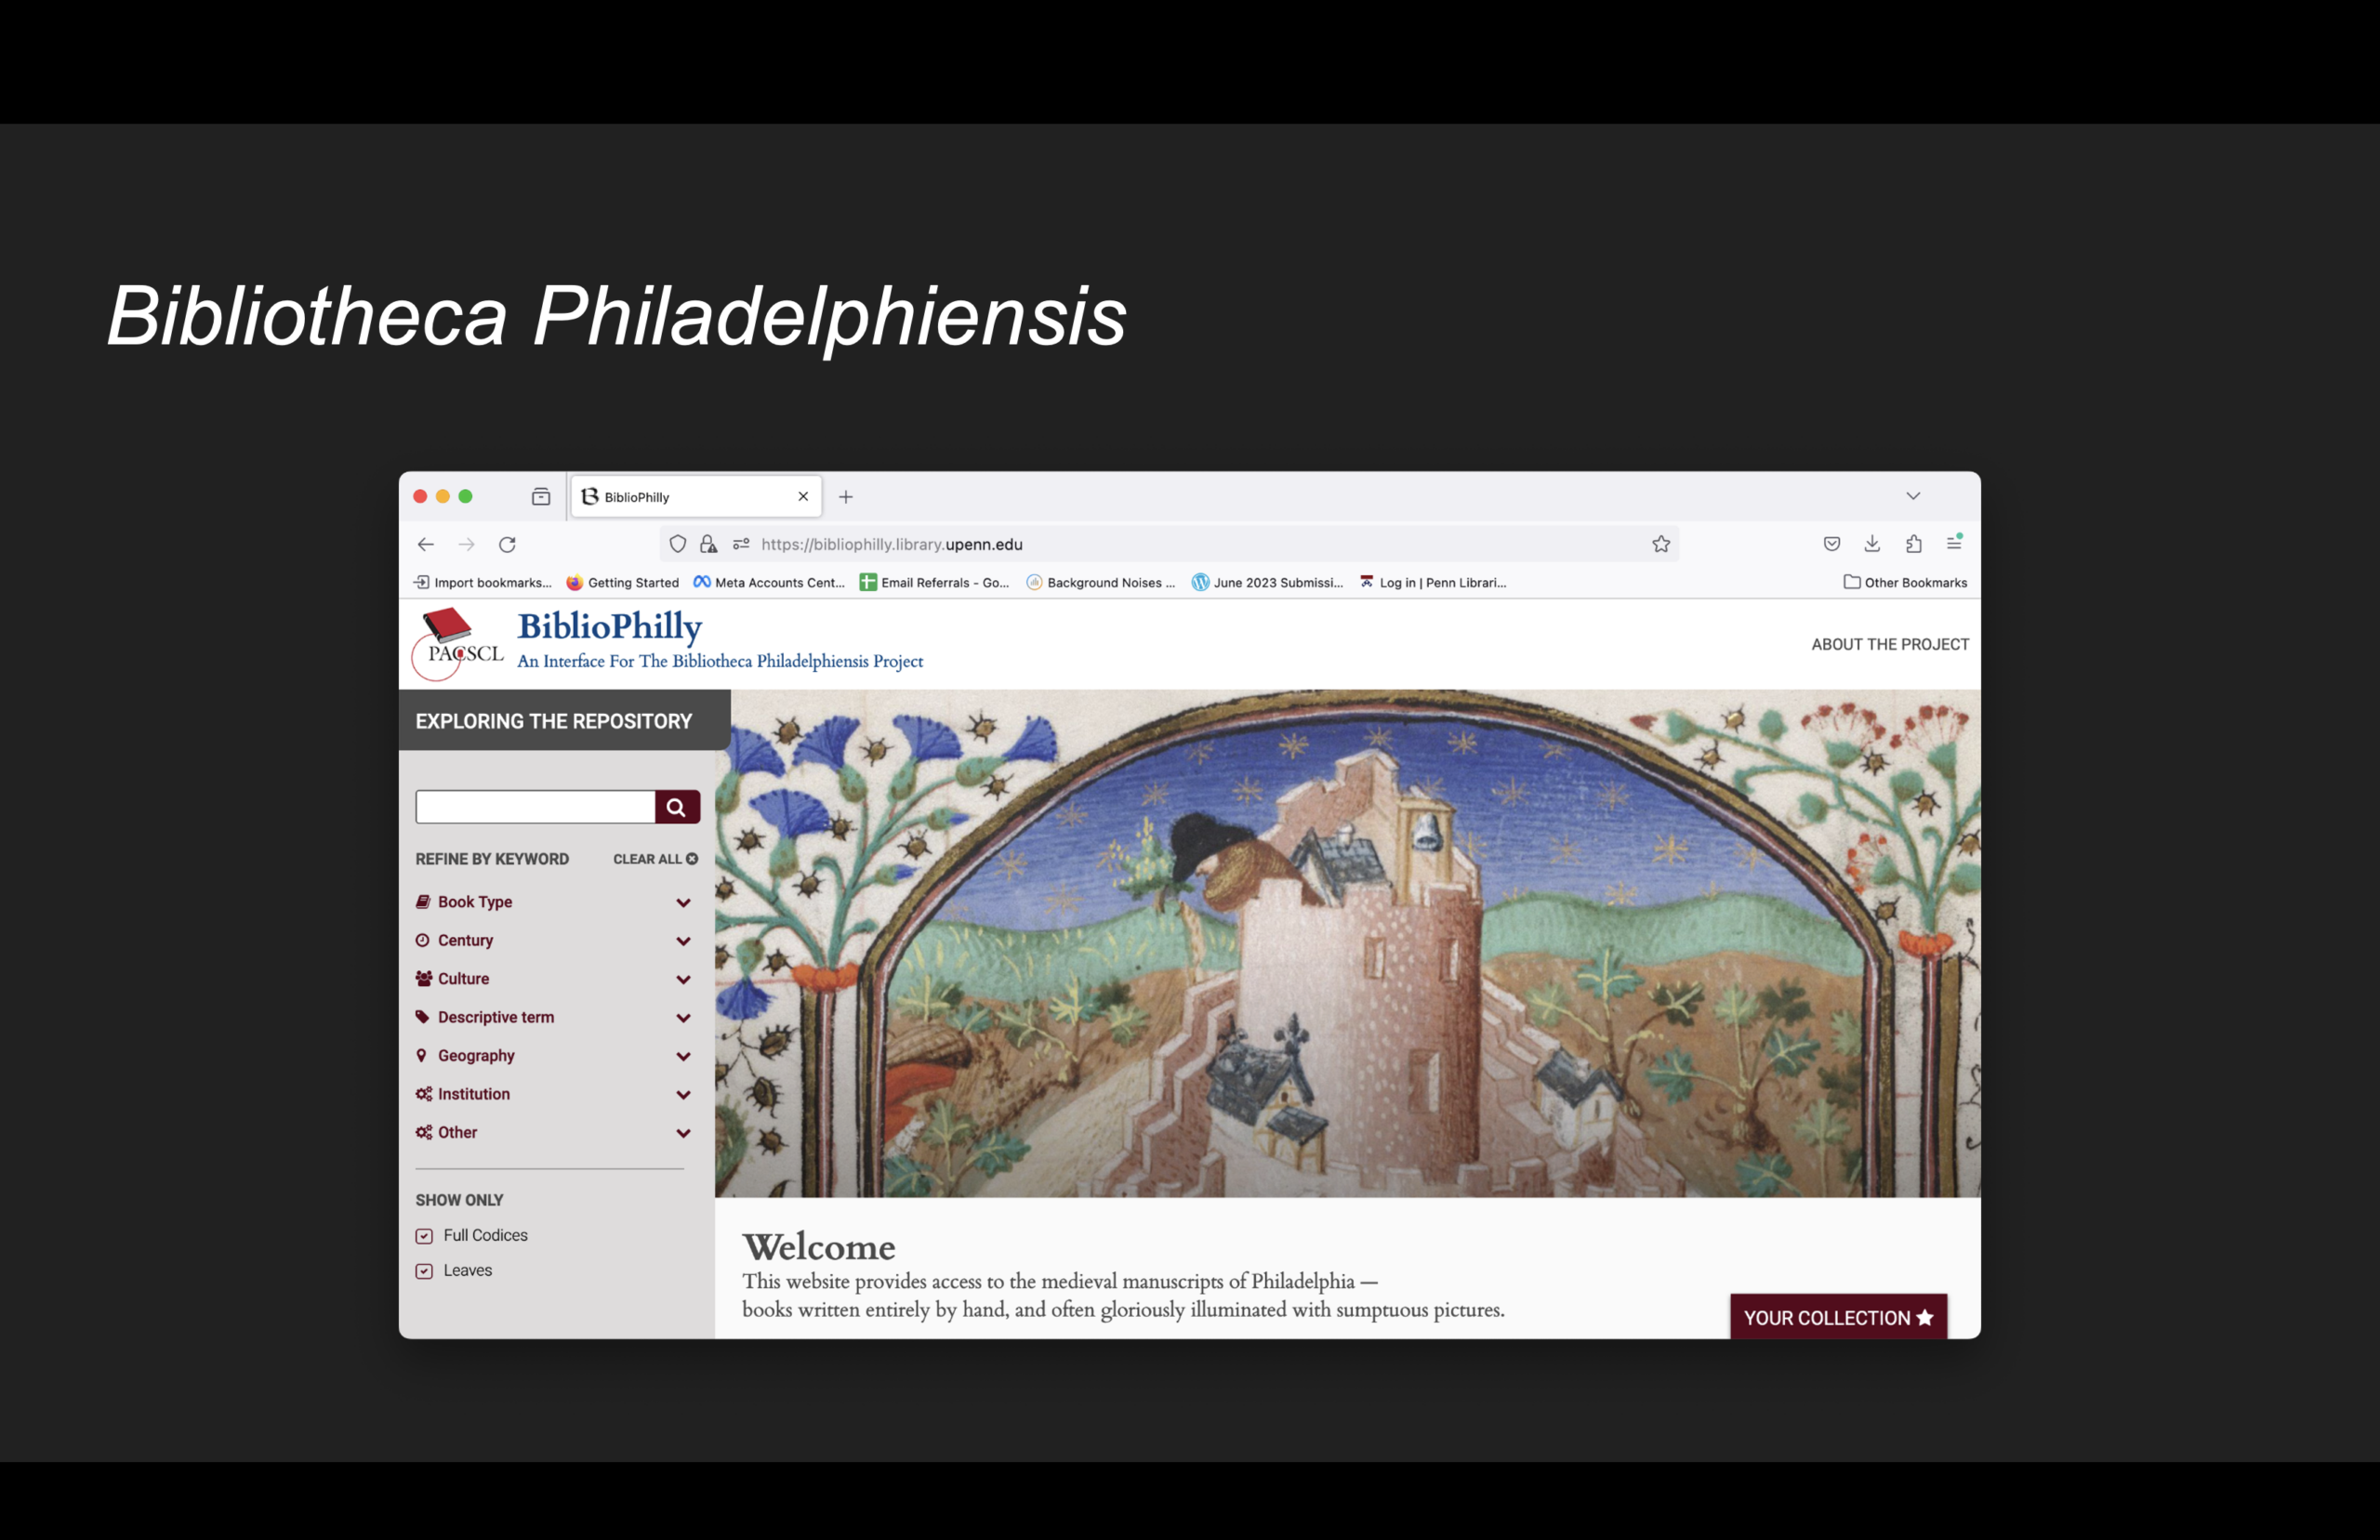
Turning to the United States, the Bibliotheca Philadelphiensis project (BiblioPhilly) provides another example of what can be achieved through external funding and institutional collaboration. Organized by the Philadelphia Area Consortium of Special Collections Libraries (PACSCL), the project ran from 2016 to 2019 with funding from the Council on Library and Information Resources (CLIR), supported by the Andrew W. Mellon Foundation. Fifteen institutions in and around Philadelphia participated, making their medieval and early modern manuscript collections available through a shared digitization effort.

BiblioPhilly brought together 15 institutions from across Philadelphia, institutions with very different collections and resources. The project made 475 codices, along with approximately 1,700 leaves and cuttings, available online. The Free Library of Philadelphia contributed the largest number of manuscripts, while other participants included university libraries, museums, and smaller special collections repositories – some of which own only one manuscript. Some institutions contributed manuscripts digitized specifically through the grant, while others made previously digitized materials available through the project. The resulting collection brought together material that had previously been dispersed institutional collections, creating a much more comprehensive picture of the region’s manuscript holdings.

The project depended on more than grant funding alone. BiblioPhilly essentially acted as a consortium within a consortium, a subset of PACSCL dedicated to medieval and Renaissance manuscripts. Members of the project consortium contributed more than their books. Lehigh University provided administrative and fiscal oversight, Penn Libraries undertook much of the digitization and hosted the images through OPenn, and every institution provided cataloging and metadata support, helping to make the manuscripts discoverable and usable as well as visible.

BiblioPhilly illustrates several of the same principles we saw in e-codices and the BVMM project: digitizing complete manuscripts, defining a manageable regional scope, and building a consortium that can pool expertise and resources. In Philadelphia, collaboration meant that institutions did not need to develop entirely separate digitization infrastructures or raise funds independently for individual institutional projects. Instead, they could participate in a coordinated effort that made their collections part of a larger digital resource. The project demonstrates how external funding, combined with an existing institutional network and shared technical infrastructure, can bring dispersed collections into a single (virtual) collection.

Shifting focus, I want to return to Paul’s second claim:

“Early manuscripts, vernacular manuscripts, illuminated manuscripts, and those with illustrious provenance are at the front of the queue for digitization.”

Briefly, it is not difficult to see the truth in Paul’s claim. Looking again at my master’s paper work from 2002, four projects representing some of the earliest full-manuscript digitization illustrate all four of these points:

Early Manuscripts at Oxford University: included some of the earliest manuscripts containing Old English (including Junius 11, ca. 1000)

Electronic Beowulf: Cotton MS Vitellius A XV, Nowell Codex, ca. 1000, written in Old English, formerly owned by Laurence Nowell and Sir Robert Cotton

The Aberdeen Bestiary: ca. 1200, lavishly illuminated

The Magna Carta (British Library, Cotton Augustus II. 106):  one of four copies authenticated with the Great Seal of King John, 1215

Clearly, early in the great experiment of mass manuscript digitization, there was a focus on early, vernacular, illuminated manuscripts with illustrious provenance. It would be interesting to see if that trend still remains today. But that’s not what I am going to do. Instead, I want to complicate this by looking at another vernacular language, and how surviving manuscripts in this language have been treated when it comes to digitization.
While compiling information during the early stages of this work, I noticed that Wales was represented by only one institution in DMMap, the National Library of Wales, despite the fact that Welsh manuscripts are held by institutions throughout Wales and beyond. Welsh is the vernacular spoken in Wales, and I was curious to see how well represented Welsh-language manuscripts are in digitized collections, in Wales and elsewhere.

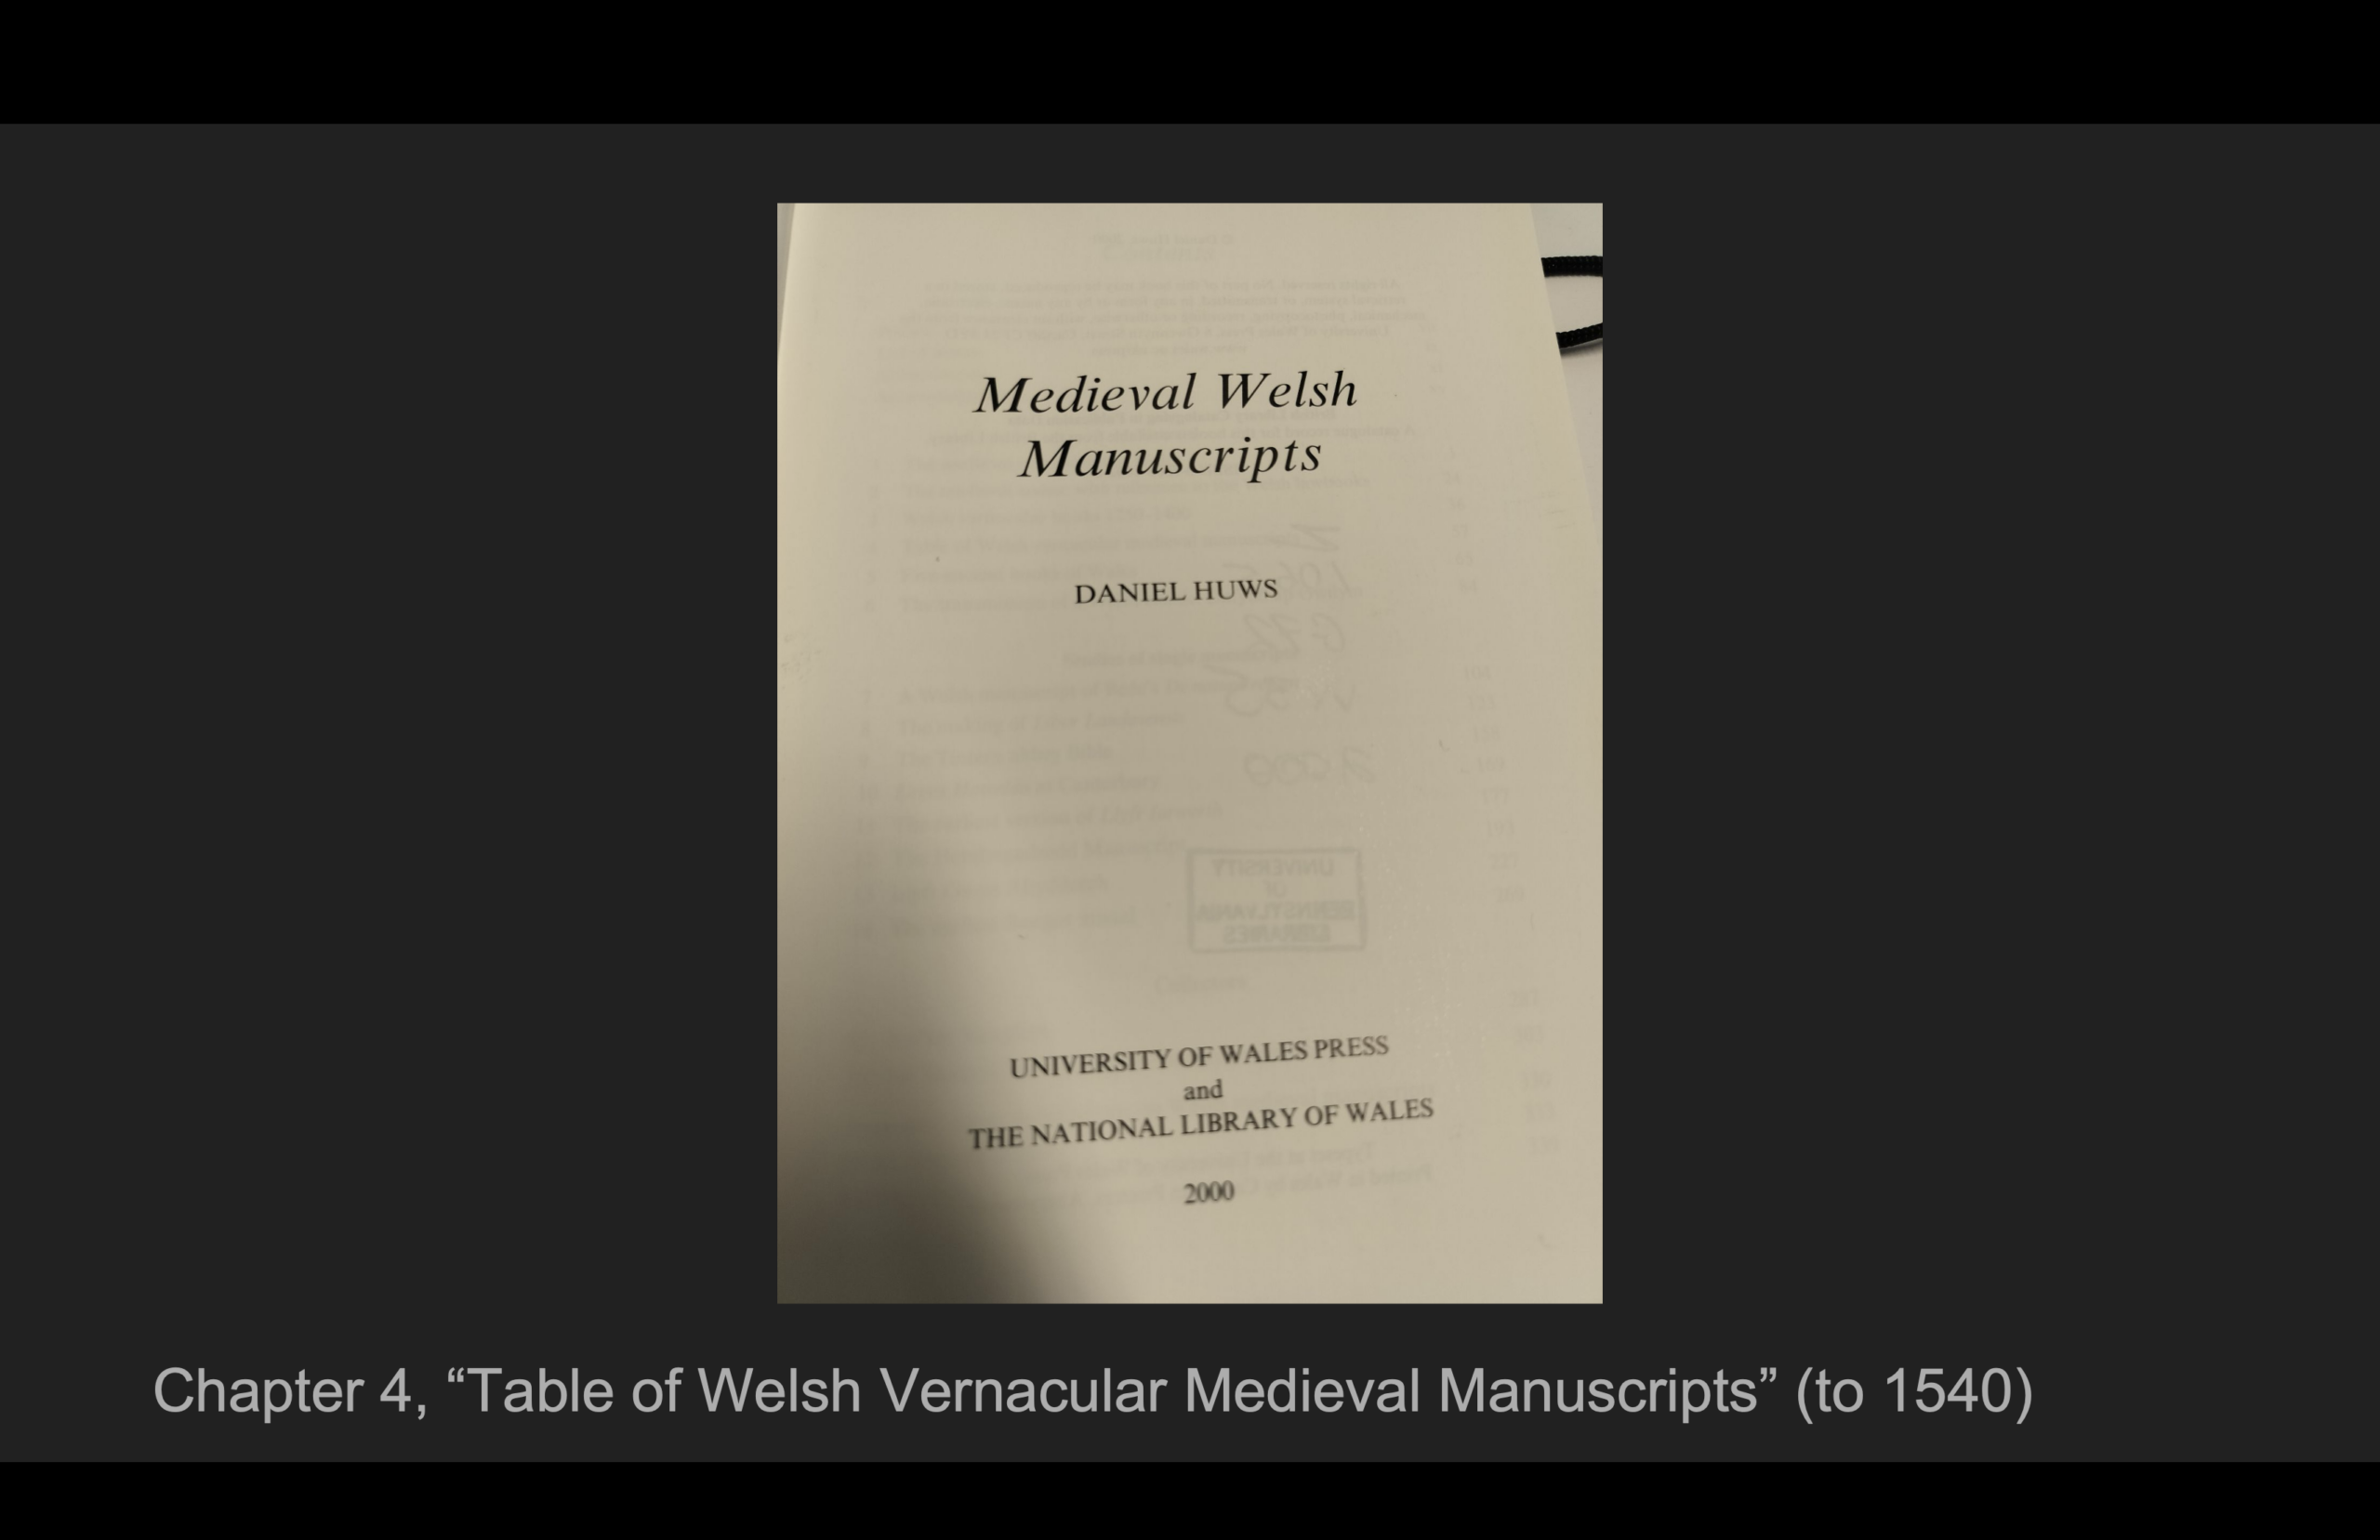
I turned to Daniel Huws’ book Medieval Welsh Manuscripts (University of Wales Press and the National Library of Wales, 2000) on Welsh vernacular manuscripts, in particular chapter 4, “Table of Welsh Vernacular Medieval Manuscripts” (to 1540). There are 174 manuscripts in this list. Of these, only 64 had been digitized as of November 2023.

Institution#manuscripts#digitized
National Library of Wales13054
British Library200
Cardiff, Central Library (now Cardiff University?)80?
Jesus College, Oxford (on deposit in Bodleian)76
Bodleian Library22
Cambridge, Trinity College10
Cambridge, Corpus Christi College11 (Parker on the Web)
Shrewsbury School10
Glasgow University Library10
Bangor University10
Bodorgan (private collection)10
Library Company of Philadelphia (?)10
Rylands Library, University of Manchester10

The distribution is strikingly uneven. The National Library of Wales accounts for 54 of these digitized manuscripts, while the British Library holds 20 manuscripts on the list and has digitized none of them. Other repositories have similarly limited digital coverage: six manuscripts at Jesus College, Oxford, were available through Digital Bodleian, along with two at the Bodleian itself and one at Corpus Christi College, Cambridge. Several other institutions hold Welsh vernacular manuscripts, but none of the manuscripts in my list at those institutions have been digitized.

This is a problem that complicates Suzanne Paul’s assertion that vernacular manuscripts are among those “at the front of the queue for digitization.” Which vernacular manuscripts are we talking about? Frankly, I assume the context of her paper is England, and thus she is talking about English vernacular manuscripts, which do appear to be prioritized in digitization efforts in England and elsewhere. (A full study on this would be interesting!)

Welsh-language manuscripts do not appear to have enjoyed the same priority. The figures suggest that a manuscript’s vernacular status alone does not explain its likelihood of being digitized; language, location, institutional resources, and the historical circumstances of a collection all matter. The situation is especially striking when we consider manuscripts held in repositories in England. The British Library’s Welsh manuscripts remain unavailable in digital copies, despite the institution’s substantial digitization activity and the importance of these manuscripts to Welsh literary and cultural history. This disparity invites us to consider the longer history of the relationship between England and Wales, including the unequal power relations through which Welsh language and culture have been marginalized. I would not argue that the figures alone establish a direct causal relationship between that history and contemporary digitization decisions. But the pattern raises important questions about whether the priorities and structures of digitization reproduce older inequalities in practices and policies of cultural heritage digitization.

There is also an economic dimension to this problem. Several institutions in Wales hold medieval manuscripts, but many have only a handful, and the resources available to digitize them are not necessarily comparable to those of larger national and university libraries. Even when a collection contains only one manuscript, digitizing it still requires equipment, staff time, infrastructure, and long-term digital preservation. A national library with an established digitization program can make substantial progress, but smaller institutions may struggle to make their holdings available without external funding or collaborative support. The Welsh example therefore brings together both of the questions raised by Paul: funding affects what can be digitized, and the assumptions guiding selection affect which collections receive attention. The result is that manuscripts can remain digitally invisible not because they lack cultural or scholarly significance, but because the institutions that hold them lack the resources—or the incentive—to make them accessible.

In conclusion, these examples suggest that the manuscript digital divide is shaped by more than the availability of external funding or the perceived significance of individual manuscripts. Switzerland’s e-codices project, France’s BVMM, and Bibliotheca Philadelphiensis demonstrate how sustained funding, a clearly defined scope, and collaboration among institutions can support digitization at scale, including for collections held by smaller institutions. But the Welsh case demonstrates why we must also examine the cultural and historical assumptions that shape our priorities. If early, illuminated, and famous manuscripts are obvious candidates for digitization, and if vernacular manuscripts are supposedly among those prioritized, we need to ask whose vernacular languages and whose cultural heritage benefit from that attention. As Paul herself warns, “there is a risk that this accessibility gap will continue to widen and a new digital canon will form,” in which manuscripts available on screen become the primary objects of study while those without digital copies are overlooked. Addressing this problem requires not only more funding and collaboration, but also a critical examination of how digitization priorities are established. We need to ask not just which manuscripts have been digitized, but which remain inaccessible, whose collections they belong to, and what the consequences of that absence are for the histories we are able to tell.

Not Just “Can We?” but “Should We?” and “Why?” Understanding Digital Manuscripts as (Big) Data

Last Spring, Bridget Whearty and I published our article “Not Just “Can We?” but “Should We?” and “Why?” Understanding Digital Manuscripts as (Big) Data” in Digital Philology. Here is a taste of that, and a link to the open access copy if you would like to read more.

Abstract: It has been over a decade since the runaway popularity of “big data” hit industry and academia in the early 2010s. Today, big data and the artificial intelligence (AI) programs that feed on them are no longer being embraced with quite as much enthusiasm. With this growing awareness of the darker sides of (big) data and AI as its foundation, this article explores the challenges of working with datasets of digital manuscripts, particularly for those who seek to treat digital manuscripts as big data. We examine big data approaches that focus on digital manuscript images and those working with structured manuscript metadata, outlining what end-users must be aware of before plunging into the world of digital manuscripts as big data. Throughout, we emphasize the ethical and environmental costs in using machine learning and other AI approaches to analyze massive datasets of medieval manuscripts. The article concludes with a series of considerations for researchers who want to engage with digital manuscripts as (big) data.

Read more here

Coffee With A Codex as an Online Community

This paper was presented via video at the SHARP Conference in July 2025. The video is posted here, followed by a transcript. A Q&A follows the talk and is transcribed at the end of this post.

I’m Dot Porter. I’m the curator for digital humanities at the Schoenberg Institute for Manuscript Studies and the Kislak Center for Special Collections, Rare Books and Manuscripts in the University of Pennsylvania Libraries. I am sorry I can’t be here in person, but I would like to thank the SHARP organizers for allowing those of us who can’t attend in person to join virtually. So here is my recording of my talk. So thank you.

Coffee with a Codex began as an improvised outreach solution during the COVID-19 pandemic. Launched by me in January, 2021 at the University of Pennsylvania’s Schoenberg Institute for Manuscript Studies, Coffee with a Codex offers a weekly, 30 minute informal Zoom session featuring primarily medieval and early modern manuscripts. The concept was and is simple: a book, an overhead camera, and a reasonably knowledgeable host, (that’s me) and also sometimes guest hosts who actually know a lot more than I do, which is always great to have. And we engage in spontaneous commentary while turning the pages of the book. It’s basically a show and tell.

oplus_0

And here is the setup with the overhead camera arm, so you can get a look at what it looks like from my side of things. And here are a couple of shots from when I was with Sophia Adams, who was a visiting scholar and she was looking at this 15th century prayer roll. And this is a view from a camera that’s in the room.

And it’s just sort of showing us as we’re doing setup. And then when we switched to the camera view, here is what the camera saw.

So you get in that case, both the far away and the close up. But this is what view looks like when we’re the program.

Now in its fifth year, the last four having been recorded with videos posted to YouTube and made available in the past events area of the webpage, Coffee with a Codex has grown into a fixture for a loyal group of manuscript enthusiasts, drawing between 25 and 40 attendees each week, depending on the topic of the manuscript. Many of these people are regulars.

In contrast to highly produced asynchronous content, Coffee with a Codex emphasizes synchronous, intimate, real-time engagement. But perhaps most notably, it has fostered a sense of community among an audience that spans disciplines, professions, and continents. This paper examines Coffee with a Codex through the lens of its 2024 participant questionnaire, focusing on how viewers experience the program and how they perceive its community aspects. The findings reveal not only deep appreciation for the program’s content and delivery, but also a strong sense of belonging and shared purpose.

Coffee with a Codex emerged from a long-standing SIMS commitment to integrating manuscript studies with digital engagement. Previous initiatives like Video Orientations, these are two to three minute videos that are posted to YouTube and also linked to our catalog records, which provide brief formal introductions to manuscripts. And Virtual Classroom Visits, virtual in-person curated manuscript visits with classes. Had already tested methods for remote object-focused teaching. But the pandemic, with its widespread restrictions on physical access, created both necessity and opportunity. Coffee with a Codex was built on that foundation, a lightweight, scalable, and personable format made possible by institutional support, smartphone cameras, and the willingness of myself and my colleagues at SIMS to be open to what was, at the beginning, very much an experiment. As my colleague, Nick Herman, Schoenberg Curator of Manuscripts, and I describe in our co-authored chapter in Mobile Heritage, which was published this year, “Coffee with a Codex represents a shift in manuscript outreach. Rather than relying on two-dimensional facsimile databases, which we also have many of at SIMS, the project returns attention to the physicality of the book, its weight, movement, texture, and sound. In doing so, we challenge the assumptions about access, audience, and authority.

Coffee with a Codex differs significantly from asynchronous content. It is ephemeral, participatory, and anchored in shared time. Its low threshold design, that is free registration, no prior experience, and short sessions, opens manuscript experiences to broader audiences. Participants are invited to type questions in the chat, which I repeat for the camera. As the recordings on YouTube don’t include the chats, neither do they include the attendees’ video and answer as I can. And here is the saved chat from our most recent event from last week.

And I’ve color coded the bars that are covering up the names. So you can see that there is one person. This was actually this person’s first time attending. So he had a lot of questions and a lot of things to say. You can see my colleague, Amey Hutchins, Manuscripts cataloging librarian, she attends sort of as my assistant and she’s there answering questions and then a couple of other people are chiming in and we have beginners. We have people saying things like that big red S looks like it was waiting for more decoration because we had a sort of, you know, lonely looking red colored initial with a lot of space around it. We’re trying to figure out what’s happening. Um, here’s someone asking me to zoom in on the lettering because we do have folks who are very interested in the letter forms and want to see that, so there’s a wide variety of folks and I’m very welcome to like comments and questions on this sort of thing. It’s one of my favorite, actually favorite parts of the event. But as one viewer wrote in response to the questionnaire, “I am not in the library or manuscript worlds, but I love the history of books and manuscripts.” That statement is emblematic of Coffee with a Codex’s power to welcome the curious and not just the credentialed.

So the 2024 Coffee with a Codex questionnaire was distributed via the program’s mailing list in the last months of the year. It included multiple choice and open-ended questions about attendance habits, asynchronous viewing, interest in online communities, preferred platforms and reflections on the program itself.

In total, we received 60 responses. This represents a self-selected group, many of them longtime participants. So the results aren’t statistically representative, but I really wanted to just hear what people had to say. The range and richness of the qualitative feedback provide valuable insight into the affective, intellectual and communal dimensions of coffee with a codex.

So what are some findings?

So the rest of this is basically going to be quotes, quotes from people, which is great. Participants frequency of attendance varied with most describing themselves as regular but flexible viewers. So Here are some examples. I try to attend when my schedule allows. I’m not able to attend as often as I would like. I wish I could come more often. I’m the department head. We all know how that is. As a full-time medical school faculty member, it’s hard for me to make all the talks.

And that’s also nice to see, right? Because a medical faculty member is not, that’s not English, it’s not art history, but they’re still interested in coming and I love that. This variability underscores the value of the recordings which some participants watch.

When live attendance isn’t possible, although the responses imply that we need to do better maybe with marketing the videos as an extension of the live sessions. So I think the recordings are good when I can’t come. And then here’s this responder who didn’t even know. I didn’t I know you’ve had recordings on YouTube and I’m going to check them out.

Respondents overwhelmingly affirmed Coffee with a Codex as a meaningful community experience. There were a lot of these. I love it. I feel like I’m part of a group that shares the same love and passion for rare materials as I do. An intelligent, cordial gathering. Most welcome. It’s lovely. That and Amey are a wonderful team. I look forward to this presentation. I like it as a gateway to a much needed weekend. Some participants also articulated a desire to grow the community. I am a 2025 MLIS candidate. I love it. You’re doing a great job. I tell my classmates. I tell librarians. I tell archivists. I want everybody to come. I belong to two international interest groups. I encourage you to test options for growing and keeping younger followers.

And yes, this is something I really want. People to come who are sort of new to manuscripts, and I want them to feel welcome, so that’s nice to see. Thank you for this wonderful program. It is appreciated that you have this group, and I have shared it with various friends.

Others expressed appreciation for Coffee with a Codex’s educational value. I look forward to these friendly meetings, which enrich my own research. And some framed the experience emotionally. Being transported each week to another country and century is wonderful. It puts the hardness of current events into some perspective.

And that is particularly nice to see because the world is really terrible right now. And my response to that has been to focus on bringing joy where I can. Not that I’m ignoring what’s happening in the world, but maybe for a half hour, we can focus on something that’s beautiful. And so I like to see that other people are doing that too. And then, of course, I love Coffee with a Codex. It’s such a lovely break in the week.

The responses suggest that Coffee with a Codex has grown beyond its original format into what we are defining through this session as a community of the book, a group formed around shared engagement with physical books. This, I think, makes Coffee with a Codex community distinct from Brian Stock’s textual communities, which I read a little bit about as I was preparing this. I didn’t think it really fit, but that’s nevertheless an obvious comparison that may be worth further analysis. Participants are not just watching. They’re participating in a ritualized event guided by an expert and joined by others who return week after week.

Importantly, I think, Coffee of the Codex attracts both traditional and non-traditional audiences, including attendees with creative rather than scholarly interest in manuscripts. Several respondents identified themselves as calligraphers, bookbinders, or artists with specific interests in material and visual details. So here are a couple of quotes from them. I’m a calligrapher and bookbinder, so seeing the letter forms is nice. And I always, I do, I talk about the bindings. I’m always pointing out things with that because I’m very interested in structure. I’m calligrapher and the letterforms are a major interest. And then I love seeing the art and the marginalia and the creatures. We don’t actually have a whole lot of manuscripts like that. But when we do, we look at them and that’s great.

These specialized comments demonstrate that Coffee with a Codex offers not just access, but also inspiration, potentially sparking new questions and creative applications. The community appears to be intentional and sustained rather than incidental. The program’s format, which is live, unscripted, personable, is designed to foster trust and continuity. As host, I am not a disembodied narrator but a regular presence, and the objects are not abstractions but are touchable and audible things.

In the 2024 questionnaire with a view towards expanding the community out of the weekly Zoom events, I asked about interest in community platforms, specifically Slack, Discord, or Facebook groups. There was definitely interest, but no clear consensus. One respondent wrote, I only know Facebook. I suggest you go with whatever is more likely to attract the largest number of participants. Yes, which is smart, especially among students and up and coming professionals. And then another cautioned, I would vote for Facebook, but since the last turn to the extreme, right? I don’t intend to use the platform. The other two, I don’t know.

This reflects a broader digital challenge, how to build community in a fragmented platform ecosystem, especially when we do have these sort of political concerns about what these platforms are supporting. Um, so we haven’t moved forward with any platform, although I am still interested in the possibility of doing this. And I think there would be a welcome in our, um, regular community as well.

I also think there are broader implications for Coffee with a Codex. It offers a compelling model for other institutions. It’s a repeatable, low cost, high touch format for engaging communities with rare materials. Its success depends not on scale, but on presence. The act of showing up each week to handle a book with care on camera for whoever wants to look.

In conclusion, Coffee with a Codex began as an emergency workaround and evolved into a beloved program with a committed audience. As the 2024 survey shows, Coffee with a codex isn’t just about manuscripts. It’s about people. It has created a rare space for shared looking informed listening and quiet joy. One participant summed it up very well. Your tireless dedication is much appreciated. Please don’t stop. I love it, and I’m not going to stop. So thank you very much for listening.

Q&A

Hi, everyone. I’m sorry I can’t be there in person to answer questions. So I asked Liz and Bridget to send me a few questions, and maybe they’re questions that you have. So I’ll do that now.

The first question, which is a general coffee with a codex question, How do you select which manuscripts to showcase when?

There’s not a lot of science to it. I have a spreadsheet where I put manuscripts as I come across them. Maybe I’ll be doing a virtual classroom visits, or I’ll be doing some other kind of project. I curated an exhibit last year. And as part of that, I looked at a whole lot of manuscripts from the collection, and I added them to the list, and then I just sort of schedule them as they come up. I do try to have a mix in the schedule, so the next couple of weeks I actually had two 15th century Italian manuscripts kind of together. We do have a lot of 15th-century Italian manuscripts in the collection so I guess it’s forgivable, but I try to. Have some variety, especially in terms of cultural background and language and that kind of thing. So I’m not just doing Latin manuscripts all the time. Although this past year, I tried to be a little more systematic. I did a search of our catalog by date of publication, which is the date that we have dated the manuscripts to. And so this year, there were a lot of early manuscripts. But again, I tried to mix them up. So you’d have like one of our early Latin ones, and then followed by like one our early Arabic ones, that kind of thing. So but now I’m sort of back to being a little bit more piecemeal, which I think is fine. I don’t, you know, I try not to stress about it too hard, except in terms of being having that variety. I will say, as I have guest hosts, I have I now have some regular guest hosts. So Louis Meiselman is our Judaica cataloger, and he picks his own manuscripts. It’s usually whatever he’s been cataloging. I also have graduate students who have guest hosted with manuscripts that they’ve been working on, so obviously they pick them. And occasionally, my colleague Nick Herman, who’s our curator of manuscripts, he will also pick his own manuscripts. And I like that too, because then I don’t have to be responsible for making the selection. But that’s a good question. So that’s how that goes.

Next question. In the range of people attending, do you find more people wondering about content or is it mostly a materiality crowd? So it’s a little bit leading, like I’m little bit leading because I am a materiality person. And I am not primarily a content person. It’s not a secret. I, and I often say it, like at the start of the event, I’m like, look, like especially if it’s something, like if it was an Arabic manuscript or a few weeks ago, I did some Arabic and Coptic, like I can’t read Arabic, I can’t read Coptic. I can not read a lot of languages. And so if people have like really detailed, if they want to see what a particular page says, I can’t help. Very frequently, there are other people on the call who can, because they’ll come and know more than me, which is fantastic. And so then that can sort of help out with the content part. But I’m very much materiality. If there are folks who are really content, they just have to put up with me talking about materiality, and I think for most people, that’s fine. So as a sort of self self-selects a little bit, and it’s hard for me to say, what people are actually coming for. All right.

Next question. Who are your attendees? Mostly already manuscripts people, or do you find yourself working with advanced professionals and totally untrained lovers of manuscripts? And how do you engage that full range?

I think that presentation actually answered the question. And it is like a broad swathe of experts and also newbies and also artists, which is great. I know that there are some folks from the Society for Creative Anachronism too who come. So it’s a great variety. How do I engage? I think I engage by sharing my knowledge, which, again, tends to be material, and also by making it a conversation. I’m not giving a lecture. I’m like, here’s the thing, ask me questions. And people do ask questions in the chat, as you saw from that one screenshot. You know, there’s very much a question and answer and also sharing knowledge and conversation. And I think that helps a lot. It helps me make people comfortable. Another thing that I do is I’m not afraid to admit when I don’t know something. I think, that’s a really important aspect, being willing to say when I don’t know something. And I think that makes the experts more willing to step up and share. And it makes people who are newbies and maybe don’t know as much feel more comfortable, like, oh, she’s the person who’s leading the event and even she doesn’t like know everything. And I think that can be really helpful. Good question.

So the last question, affect, I love affect. You are an enormous lover of manuscripts as well as highly trained and experienced. How much of that love do you share in Coffee with a Codex versus say Inside My Favorite Manuscript podcast (which is a podcast I hosted a few years ago. I don’t do anymore, sad.) And how do you decide the balance of pleasure and rigor? So I’m all pleasure. It’s all about like, Let’s have fun. I actually think about it as manuscript fandom. I have a long history in fandom, and I do feel like what I do is a type of fandom work. That said, I don’t want to lie about the stuff, which is one of the reasons why I’m not afraid to say when I don’t know something. The thing that I have is I have access. Right, like I am a curator in this library, and we have these incredible collections. And I don’t know everything about everything in the collection, and I don t have to, because I have a camera and I can show it on Zoom. And I feel like that’s the least that I could do. For me, it really is about like sharing this amazing thing that we have with the world, even when I can’t tell you every single thing about it. But the community, you know, that’s sort of where the community can kind of step in. And it’s one of the reasons why I also love having guest hosts who do tend to be more knowledgeable than I am. So that’s really valuable. Yeah, so great question. And I think that was the last one.

So if you have a question that I didn’t answer, if you want to know more about Coffee with a Codex, if you’re interested maybe in setting something like this up at your institution, I would love to That is, yes, dorp at upenn.edu. And again, I’m really sorry I couldn’t be there in person. I’m with you in spirit. And I hope you all have a wonderful day.
 

Speculative Codicology

In March 2025, I presented a talk for the “Medievalia at the Lilly Library” annual event called “VCEditor as a Tool for Speculative Codicology.” I started the talk with a description of the VisColl Project, which is concerned with the practice and theory of modeling and visualizing the physical construction (aka collation) of codex manuscripts. Next, I talked about VCEditor, which is the current version of the software we use to build and visualize models (using the VisColl Data Model). 

Continue reading “Speculative Codicology”

Addendum: Full citations for Specific Knowledge post

This post serves as an addendum to Specific Knowledge: Cassandra Daucus on Manuscripts, published by From Beyond Press.

If you’re here because you read the Specific Knowledge post and you’d like to know more about the manuscripts in the figures, welcome! Below you’ll find full citations, links to the catalog records and digital facsimiles, and videos where they exist.

All the books featured in the post are from the collections of the Kislak Center for Special Collections, Rare Books and Manuscripts at the University of Pennsylvania Libraries.

Continue reading “Addendum: Full citations for Specific Knowledge post”

Collection Sharing as a form of Digital Collections Security

This blog post was originally conceived as a contribution to Now You See It Now You Don’t: Sustainable Access in a Digital Age, an event organized by the Bodleian Library and held on Zoom on February 7, 2024. Although my name appears in the list of contributors, I caught the flu that week and wasn’t able to attend. But I was prepared, and even though I’ve no doubt other people there said similar things, I wanted to post this for FOMO if for no other reason. This post consists of screenshots of my slides, and accompanying notes that explain my points further.

Continue reading “Collection Sharing as a form of Digital Collections Security”

Modelling the Historical Manuscript: Theory and Practice 

Presented in the session Materiality of Manuscripts III: The Codex at the International Medieval Congress, Leeds, UK July 5, 2022 

Good morning, good afternoon. Thank you to Katarzyna and Kıvılcım for organizing these sessions on Materiality of Manuscripts for IMC 2022. I’m Dot Porter and I’m going to talk about modeling the historical manuscript theory and practice.

Continue reading “Modelling the Historical Manuscript: Theory and Practice “